Vector Database Review Guide for Enterprise RAG

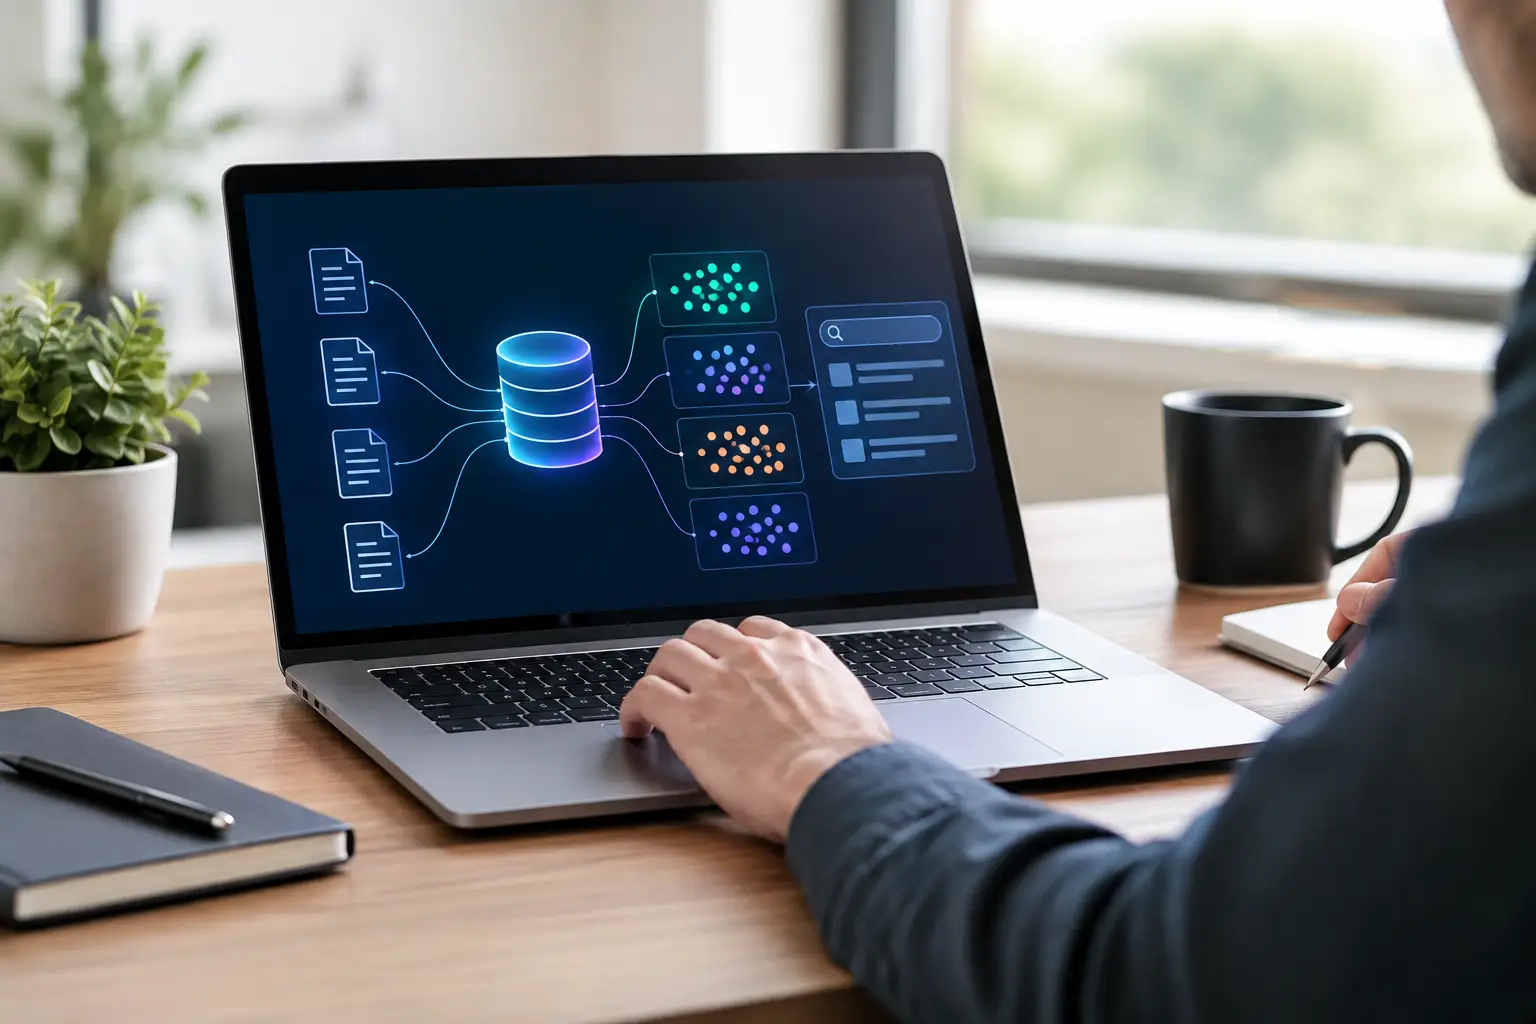
A vector database review guide for assessing retrieval quality, operating cost, governance and deployment risk before committing enterprise RAG workloads.
[+] REVEAL DYNAMIC STRUCTURAL DIGEST
01. CORE PARADIGM: FOCUSES ON VARIABLE INFERENCE PRICING MARGINS AND AUTONOMOUS EXECUTION LOOPS RATHER THAN SIMPLE CHAT DIALOGS.
02. STRATEGIC PATH: MINIMIZES Operational COGS BY ROUTING COMPUTATION TO DISTILLED OPEN SOURCE MODEL CLUSTERS.
03. RISK ANATOMY: PROPOSES HUMAN-IN-THE-LOOP SAFEGUARDS AS GLOBAL DATA POLICIES AND GPU SCARCITY FRAGMENT INTEGRATIONS.
A vector database review guide should begin with a harder question than which engine has the fastest benchmark: what retrieval failure can the business afford? In enterprise RAG, the vector layer determines which evidence reaches the model, how quickly it arrives, where it is processed and what it costs to maintain. A poor selection does not merely add latency. It creates unreliable answers, weak auditability and an infrastructure commitment that becomes expensive to unwind.
The market is crowded because vector search has become a standard component of AI application architecture. Yet products that appear interchangeable in a demonstration often diverge sharply under production conditions: frequent document changes, strict access controls, multilingual corpora, hybrid retrieval, regional deployment requirements and tightly controlled compute token budgets. The appropriate review is therefore an architecture assessment, not a feature checklist.
Start with the retrieval workload, not the database
Most teams over-index on approximate nearest-neighbour performance. Recall at a given latency threshold matters, but it is only one part of the system. The relevant workload includes the embedding model, chunking policy, metadata structure, query distribution, reranking layer and the user-facing consequence of a wrong answer.
A support copilot searching a stable product manual has very different requirements from an internal research assistant operating across policy documents, presentations, source code and rapidly changing operational data. The former may favour low-cost managed operations and simple filtering. The latter may require strong hybrid search, high-cardinality metadata filtering, incremental indexing and evidence-level provenance.
Define a representative corpus before any procurement exercise. It should include duplicates, versioned documents, poorly formatted files, competing terminology and access-restricted material. Synthetic benchmark datasets are useful for engine-level comparison, but they rarely expose the retrieval pathologies that affect an actual enterprise knowledge base.
The most useful review question is not, “Can this database return similar vectors?” It is, “Can this architecture retrieve the correct, permitted and current evidence for the decisions our users will make?”
The vector database review guide: five decision layers
A disciplined evaluation separates concerns that product literature commonly blends together. These five layers provide a practical structure for technical and commercial review.
1. Retrieval quality under realistic constraints
Measure quality at the answerable task level. Begin with a labelled evaluation set containing real queries, expected source passages and relevance judgements. Track recall at k, precision at k, mean reciprocal rank and nDCG, but also inspect failure categories: stale results, semantically plausible but incorrect passages, irrelevant results caused by ambiguous terms and documents excluded by filters.
Vector-only retrieval is seldom sufficient for complex enterprise collections. Exact terminology, identifiers, legal clauses, product codes and proper nouns often benefit from lexical search. Review whether the platform supports hybrid retrieval natively, how it combines sparse and dense scores, and whether the ranking method can be tuned without rebuilding the operating model.
Metadata filtering requires particular scrutiny. A system may advertise filters while performing poorly when queries combine tenant, business unit, document type, date range and entitlements. Test filter selectivity at production-like scale. The critical metric is not only speed, but whether filtering changes recall in unexpected ways or produces unstable tail latency.
2. Write path and index economics
Read-heavy demonstrations conceal the cost of keeping an index current. Enterprises ingest documents continuously, revise policies, revoke access and delete records subject to retention rules. Assess ingestion throughput, index build time, upsert behaviour, deletion guarantees and the operational impact of compaction or rebalancing.
There is an unavoidable trade-off between query efficiency, write performance and memory use. Some index structures offer strong low-latency search but consume substantial RAM or require time-consuming rebuilds. Others are better suited to high ingestion rates but demand more compute to meet the same query target. There is no universally superior design because workload shape decides the economic outcome.
Ask for cost estimates across three scenarios: initial backfill, steady-state ingestion and peak query periods. Include replicas, backup storage, network egress, embedding generation and reranking compute. A low unit price for vector storage can be irrelevant if operational requirements force overprovisioned nodes or frequent index maintenance.
3. Operational resilience and deployment control
The database is part of an autonomous execution layer, even when its role appears passive. If retrieval is unavailable or degraded, agentic workflows may fabricate context, repeat expensive calls or fail to complete a business process. Establish the required recovery point and recovery time objectives, then test them rather than accepting architecture diagrams as proof.
Review replication topology, failover behaviour, backup restoration, upgrade procedures and observability. Teams should be able to identify whether poor answer quality originated in embeddings, retrieval, filters, reranking or the language model. A retrieval platform that exposes only infrastructure metrics leaves operators unable to diagnose the business impact of degraded relevance.
Deployment model is equally strategic. Managed services reduce operational burden, but can constrain network design, data residency and incident response. Self-managed or open-source deployments increase control, although the organisation then owns capacity planning, patching and on-call expertise. For organisations subject to sovereign localisation guidelines, the ability to specify region, encryption boundaries and control-plane exposure can outweigh minor differences in query speed.
4. Governance, permissions and deletion
Security review should focus on retrieval-time enforcement, not just encryption claims. In a multi-user RAG application, a document must be inaccessible both before and after vectorisation. Verify whether permissions are stored as filterable metadata, resolved externally or enforced through application logic. Each approach has consequences for latency, complexity and the risk of permission drift.
Deletion is another common blind spot. Removing a source document should remove associated chunks, vectors, cached retrieval artefacts and replicas within a defined service level. If index compaction delays physical removal, the organisation needs a clear understanding of what remains searchable and for how long.
Audit requirements also extend beyond database access logs. A regulated deployment may need to reconstruct the retrieved context used to generate a recommendation, including document version, chunk identifier, ranking score and applied filters. Without this record, post-incident review becomes speculative.
5. Portability and supplier concentration
A vector index is not a neutral data store. Its schema, filtering semantics, hybrid ranking implementation and operational tooling can create meaningful switching costs. The risk is greatest when application logic becomes dependent on proprietary query operators or managed pipeline features.
Portability does not require avoiding specialist capabilities. It requires an explicit boundary between durable application assets and supplier-specific optimisations. Preserve source documents, embedding inputs, chunking logic, metadata definitions and relevance evaluations in formats that can be reconstituted elsewhere. Treat the vector index as a derived asset, even if rebuilding it is costly.
Build a review process that produces evidence
A credible selection process usually has three stages. First, establish architecture fit through documentation review and a small technical prototype. Second, run a controlled benchmark using the organisation’s corpus and evaluation set. Third, conduct an operational and governance review with platform engineering, security and procurement involved before a production commitment.
The benchmark should impose realistic load rather than chasing headline queries per second. Include concurrent users, mixed query types, restrictive filters, document updates and a failure injection such as a node loss or interrupted ingestion job. Record p50, p95 and p99 latency, but place equal weight on retrieval relevance, indexing lag and operator effort.
Avoid scoring vendors with a single weighted total too early. A platform that ranks slightly lower on raw latency may be the stronger choice if it satisfies data boundary requirements, supports existing observability practices and can be operated by the available team. Conversely, an elegant developer experience may not compensate for weak tenant isolation or unpredictable costs at scale.
What executives should ask before approval
The decision is often framed as an engineering purchase when it is better understood as a control point in the enterprise AI stack. Leaders should require clear answers to four questions:
- What measurable retrieval quality is required for the intended workflow, and who owns regression testing as the corpus changes?
- What is the full cost per useful answer once storage, compute, embedding, reranking, operations and resilience are included?
- Can the organisation prove which sources informed an output and whether the user was authorised to see them?
- What is the exit path if data residency, commercial terms or product direction change?
These questions convert an ambiguous infrastructure decision into a set of operational commitments. They also expose whether a proposed RAG system is a contained productivity tool or a dependency that will sit beneath customer service, research, compliance and internal decision-making.
For WAO GPT readers, the central discipline is to treat vector retrieval as evidence infrastructure. The winning platform is not the one with the most impressive search graph. It is the one that maintains relevance, control and economic predictability as the organisation’s knowledge base and AI ambitions become harder to govern.
TACTICAL TAKEAWAYS
- 01.Contextual Assessment: Evaluate underlying data architectures prior to executing local distillation pathways.
- 02.Unit Economics Tracking: Model operational budgets on variable token queries, prioritizing open source models for static endpoints.
- 03.Sovereignty & Redundancy: Maintain local fallback parameters to prevent regional API disruptions.