Agent Frameworks vs Orchestration Layers

Agent frameworks vs orchestration layers: a decision framework for choosing control planes, managing risk, and scaling reliable AI operations safely.
[+] REVEAL DYNAMIC STRUCTURAL DIGEST
01. CORE PARADIGM: FOCUSES ON VARIABLE INFERENCE PRICING MARGINS AND AUTONOMOUS EXECUTION LOOPS RATHER THAN SIMPLE CHAT DIALOGS.
02. STRATEGIC PATH: MINIMIZES Operational COGS BY ROUTING COMPUTATION TO DISTILLED OPEN SOURCE MODEL CLUSTERS.
03. RISK ANATOMY: PROPOSES HUMAN-IN-THE-LOOP SAFEGUARDS AS GLOBAL DATA POLICIES AND GPU SCARCITY FRAGMENT INTEGRATIONS.
A production agent that can select tools is not necessarily a production system. The distinction between agent frameworks vs orchestration layers becomes material the moment an AI workflow touches customer data, executes a financial action, or must explain why a decision was made. One provides the machinery for agent behaviour; the other governs execution across a wider operational estate.
For technical leaders, this is not a vocabulary dispute. It determines where state is held, how failures are recovered, which team owns policy enforcement, and whether an autonomous workflow can move beyond a contained demonstration without creating an unpriced operational liability.
Agent frameworks vs orchestration layers: the core distinction
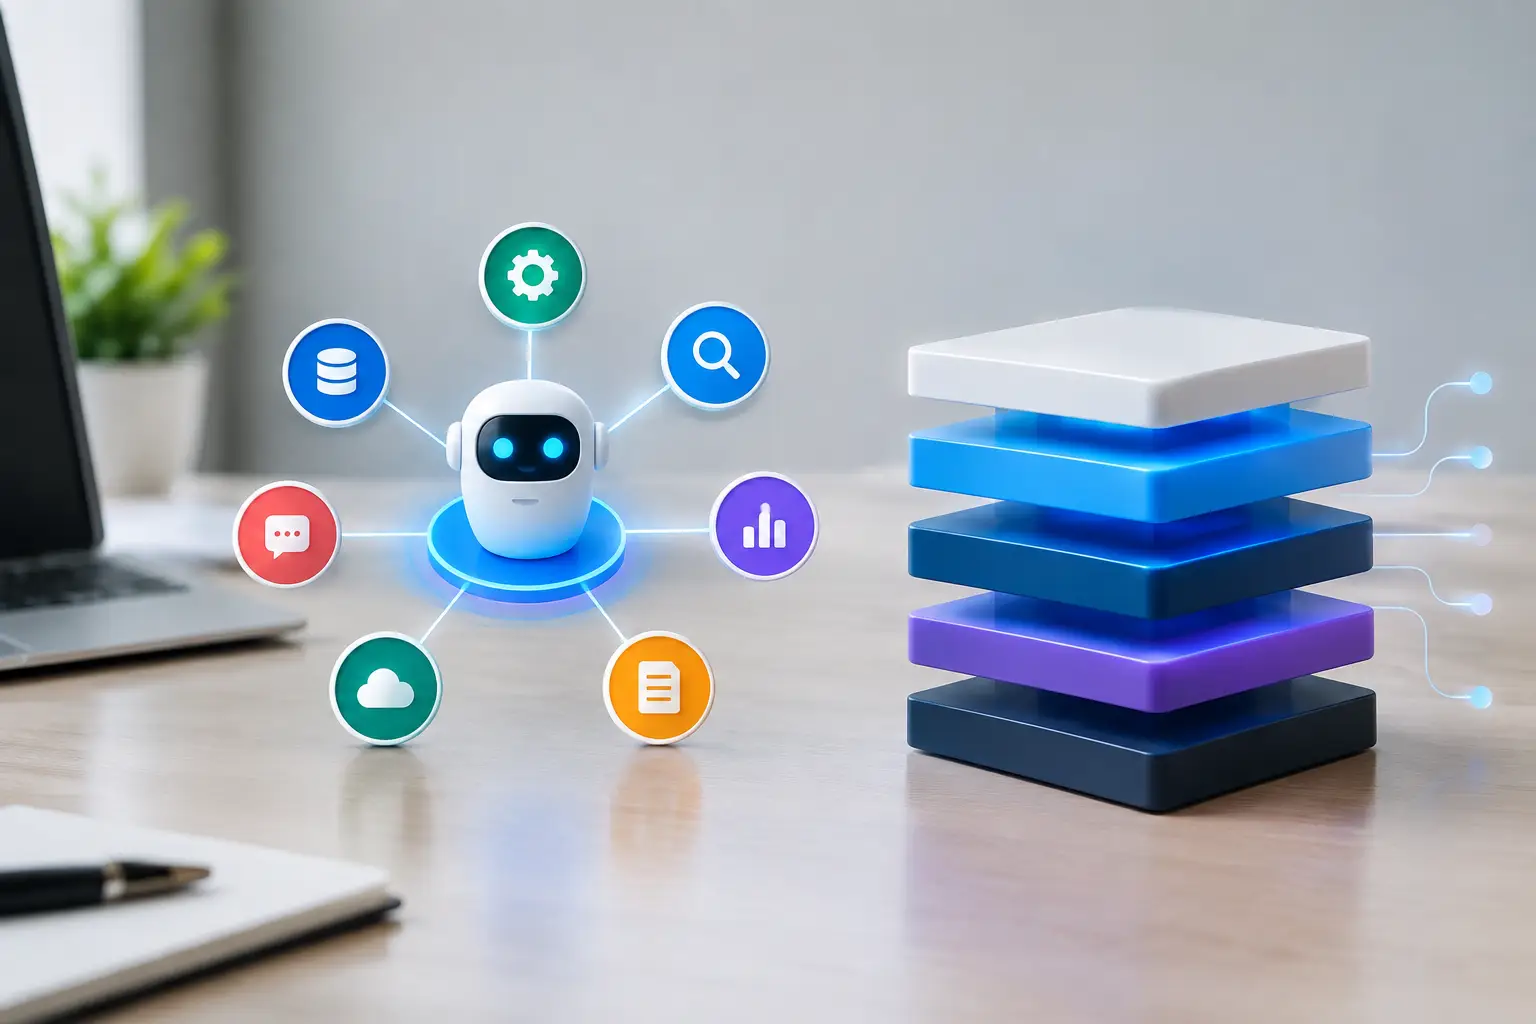
An agent framework is an application-level construct. It gives developers primitives for model calls, tool use, memory, planning loops, structured outputs, retrieval, and sometimes multi-agent hand-offs. Its purpose is to make an LLM capable of pursuing a bounded objective through a sequence of decisions.
An orchestration layer sits above, beside, or around that agent runtime. It coordinates work across services, models, queues, humans, databases, identity systems, and policy controls. Its concern is not whether the model can decide to call a tool. Its concern is whether the resulting process is authorised, observable, resumable, economical, and safe to operate at scale.
The overlap can obscure the difference. A framework may expose tracing, retries and workflow graphs. An orchestration product may advertise agentic capabilities. Yet the architectural question remains clear: does the component organise an agent’s reasoning process, or does it control an enterprise process that happens to include agents?
A useful test is to remove the LLM. If the surrounding system would still require scheduling, state management, approvals, audit records, retries and exception handling, those functions belong to orchestration. If the component has little purpose without prompt construction, tool selection and model inference, it is probably part of the agent framework.
Why the boundary matters in production
Early prototypes often place everything in one codebase. That is rational. A small team needs to establish whether an agent can reconcile invoices, triage service requests, or prepare a research brief before it invests in a control plane.
The problem begins when prototype assumptions become operating assumptions. A reasoning loop that retries after a malformed tool call is useful. It is not equivalent to a durable workflow that can resume after an upstream API outage, route high-risk exceptions to a reviewer, and retain a defensible record of each action.
This distinction has direct economic consequences. Agent frameworks optimise developer velocity around inference. Orchestration layers optimise system reliability across variable compute token budgets, rate limits, long-running tasks and downstream dependencies. If an agent repeatedly researches an ambiguous request for twenty minutes before failing at a permissions check, the cost is not merely additional tokens. It is wasted infrastructure capacity, delayed work and diminished user trust.
There is also a governance boundary. Policy enforcement embedded solely in prompts is fragile because prompts are instructions, not access controls. A mature orchestration layer can apply deterministic rules before and after inference: validate identity, constrain tool scopes, impose spending thresholds, require dual approval, redact sensitive fields and quarantine anomalous execution paths.
What belongs in an agent framework
The framework should own cognition-oriented concerns. That includes prompt assembly, context selection, structured model outputs, tool schemas, planning logic, short-lived working memory and evaluation of model-specific behaviour. It is the appropriate home for the question, “Given this task and context, what should the agent attempt next?”
Framework selection therefore turns on the complexity of the agent itself. A retrieval assistant with one search tool and a fixed response format may need little more than a thin model SDK plus application code. Introducing a substantial framework too early can add abstractions without resolving the real delivery risk.
A framework becomes more valuable where an agent must choose among multiple tools, maintain intermediate state, follow constrained plans or coordinate specialist sub-agents. Even then, teams should inspect the execution semantics rather than accept marketing labels. Does state survive a process restart? Can individual tool calls be replayed? Are outputs typed and validated? Is tracing exportable to the organisation’s existing observability stack?
These are not minor implementation details. An agent that cannot expose its intermediate decisions cannot be reliably evaluated, and an agent that cannot separate transient reasoning state from durable business records becomes difficult to govern.
What belongs in an orchestration layer
The orchestration layer should own process-oriented concerns: durable state, asynchronous execution, event triggers, queueing, retries, timeouts, idempotency, human review, service credentials, policy checks and audit trails. It should be able to treat an agent invocation as one step within a larger workflow, rather than as the workflow itself.
Consider claims handling. An agent may extract facts from documents, identify missing evidence and recommend a next action. The orchestration layer determines whether the claim is eligible for automated handling, records the model version used, pauses the case when confidence is insufficient, sends a task to an assessor and guarantees that a payment instruction is not issued twice.
That division is especially important for long-running workflows. Model calls are frequently synchronous, but business processes are not. A supplier onboarding case may wait days for documents; a security investigation may need several specialist analyses; an internal procurement request may require sequential approvals. Treating such processes as an extended chat session creates brittle state and poor recovery characteristics.
Orchestration is also where organisations can manage model substitution. If a workflow specifies capabilities and quality thresholds rather than hard-coding a single provider, operators can route tasks according to latency, cost, data residency and availability. The agent framework may still contain model-specific adaptations, but routing policy should remain visible to the teams accountable for service performance and risk.
The common architecture mistake
The recurring failure mode is to make the agent framework the enterprise control plane. It starts harmlessly: developers use its built-in memory, a local checkpoint store and a simple retry decorator. Then the same runtime is asked to coordinate confidential data, multiple departments and irreversible actions.
At that stage, the organisation inherits hidden coupling. Agent state becomes business state. Tool permissions become application configuration. Evaluation traces become incomplete audit records. Retries can duplicate actions because the runtime has no durable idempotency key. A new compliance rule requires edits across prompts, tools and bespoke workflow branches.
The inverse mistake is equally costly. Some enterprises install a heavyweight workflow platform before they have established what degree of agency is needed. They construct elaborate approval paths around what is, in practice, a deterministic document transformation. In those cases, a conventional API workflow with structured extraction and a human exception queue will be cheaper, easier to test and easier to explain.
The correct architecture depends on the uncertainty of the task and the consequences of error. High uncertainty may justify an agent. High consequence demands an orchestration boundary. When both are high, the agent should be explicitly constrained and placed inside a deterministic envelope.
A practical decision model for technical leaders
Start by classifying the action, not the model. If the system drafts content or produces internal analysis, an application-level agent framework may be sufficient, provided access remains bounded. If it changes records, communicates externally, controls funds, or makes recommendations with regulated implications, introduce orchestration controls before expanding autonomy.
Next, identify the required durability. A workflow that must survive restarts, wait for events or retain state across days needs durable orchestration. Do not confuse conversation history with process state. The former supports model coherence; the latter supports accountable operations.
Then separate probabilistic and deterministic logic. Let the agent interpret, classify, summarise and propose. Let deterministic services validate permissions, calculate entitlements, commit transactions and enforce policy. This division makes both testing and incident response materially more tractable.
Finally, establish measurement at both layers. Framework-level evaluation should assess tool selection, factual accuracy, completion rates and token use. Orchestration-level measurement should track queue latency, retries, approval rates, exception causes, unit cost per completed case and the rate of prevented unsafe actions. A workflow can score well in offline model evaluation while failing economically in live operations.
Build for replaceability, not ideological purity
The market will continue to blur these categories. Framework vendors will add workflow functions; orchestration platforms will add agent builders. That does not remove the need for clear ownership boundaries. It increases it.
A sensible design keeps agent logic replaceable, gives workflows stable interfaces, and stores authoritative business state outside the reasoning runtime. It also makes the model’s discretion explicit: what it may recommend, what it may execute, and what always requires a deterministic check or human judgement.
For WAO GPT readers, the strategic issue is simple. Agent capability creates potential operational leverage, but orchestration determines whether that leverage can be captured repeatedly under cost, security and accountability constraints. Build the agent where reasoning is useful. Build the control plane where the business must remain in command.
TACTICAL TAKEAWAYS
- 01.Contextual Assessment: Evaluate underlying data architectures prior to executing local distillation pathways.
- 02.Unit Economics Tracking: Model operational budgets on variable token queries, prioritizing open source models for static endpoints.
- 03.Sovereignty & Redundancy: Maintain local fallback parameters to prevent regional API disruptions.